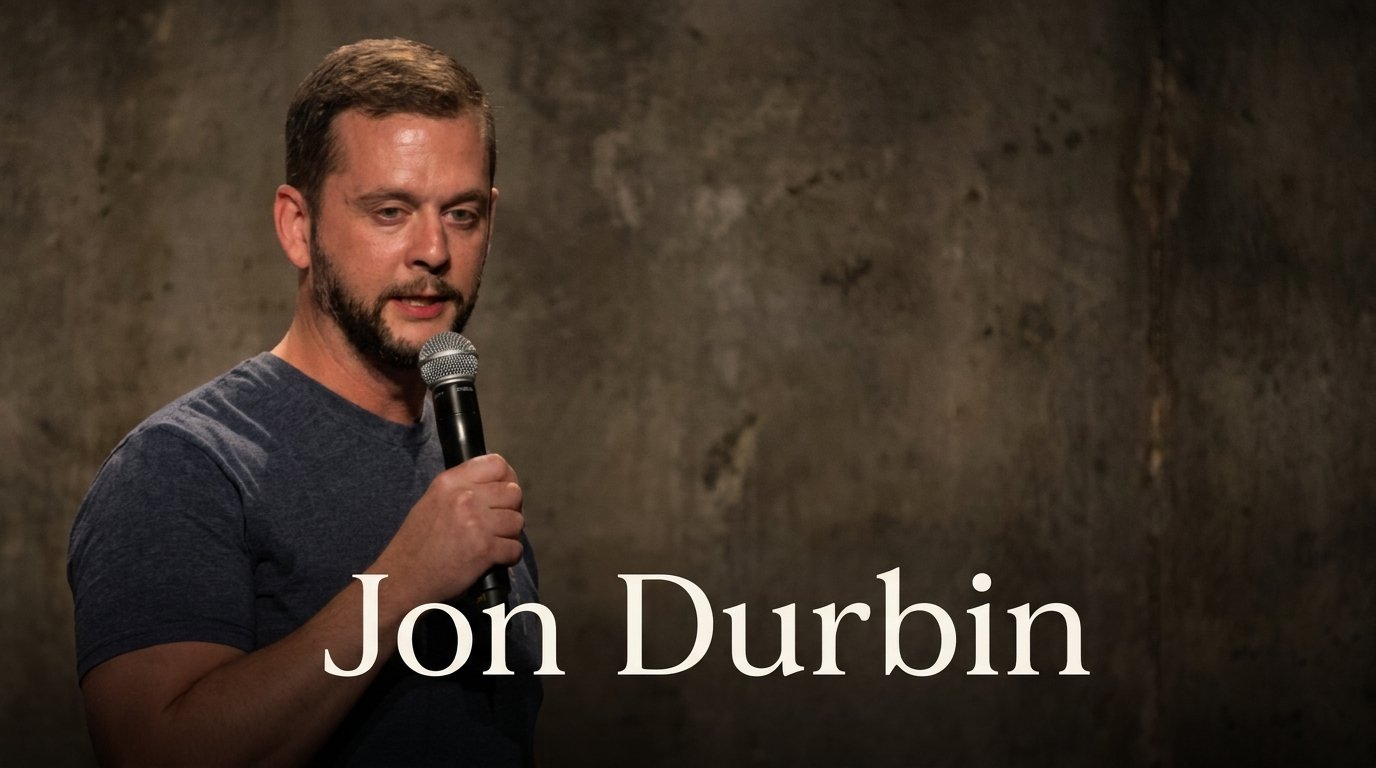
Jon Durbin of Chutes used his Exploit Summit keynote to argue that the future of open AI may depend less on building ever-larger data centers and more on finding better ways to use the compute already spread across the world.
His strongest proof point was an 8 billion parameter model trained across distributed consumer GPUs for roughly $6,500 in GPU rental costs. The same model can run locally on a phone CPU at close to 60 tokens per second, without using the phone’s GPU or NPU.
For Durbin, those numbers are part of a much bigger goal. He wants AI that can be openly trained, independently reproduced and eventually run on devices people control themselves.
Why Durbin Thinks AI Needs a Different Path
Durbin opened the talk by explaining that his interest in open AI is personal. After discussing his family and the difficult path that led to having his twin sons, he said his motivation is making sure they always have access to powerful AI without needing permission from a company or government.
From there, the keynote moved into the infrastructure problem.
AI companies are spending heavily on centralized data centers, but Durbin argued that money alone cannot solve constraints around power, hardware supply and network infrastructure.
At the same time, he believes relying on a small number of companies for models, data and compute creates another problem because users must trust those providers with their prompts, intellectual property and access to intelligence.
Chutes already approaches part of this problem through encrypted inference. Durbin said users who enable its end-to-end encryption can send prompts without Chutes itself being able to read the prompt or response. But his longer-term preference goes even further toward models that can run completely locally and even be air-gapped from the internet.
The Hard Part Is Decentralized Training
Running open models is one problem. Training them without a centralized cluster is much harder.
Durbin highlighted several issues decentralized training systems have to handle, including:
- large communication requirements between GPUs
- machines operating at different speeds
- unreliable internet connections
- malicious or poisoned training updates
- forged updates that appear legitimate
- central dependencies that can become an off switch
Instead of avoiding those weaknesses, Chutes deliberately designed around them.
The system Durbin introduced is called Parallax. Its goal is to coordinate model training across independent machines while removing as many central points of failure as possible.
That means a slow GPU, a weak upload connection or a machine suddenly disappearing should not stop the entire training run.
➛ Read more about Parallax below:
Making the Model Smaller Changes the Economics
A major part of Parallax is not simply distributing normal model training across more computers. Chutes is also changing the model architecture itself.
The model uses sparse ternary weights in parts of the network. Instead of storing normal high-precision values, many weights can effectively be represented using -1, 0 or 1, while enforced sparsity means many of those weights are zero.
Durbin said this brings storage for those weights down to around 1.125 bits per weight. It can also simplify inference because some multiplication operations can be skipped entirely.
Chutes is also training the models this way from the beginning instead of first training a large high-precision model and compressing it afterward.
The result is a model designed from day one around cheap inference, low memory usage and decentralized training.
The 8B Experiment Cost Roughly $6,500
The most interesting demonstration came from Parallax’s 8 billion parameter training run.
The run took about two days and cost roughly $6,500 using rented GPUs at normal hourly prices. That worked out to around $1,127 per billion training tokens.
The system also reached roughly 54.7% model FLOPs utilization, or MFU, despite deliberately using RTX 5090s with very different performance characteristics and network conditions.
Durbin said some GPUs were significantly slower than others and some nodes had upload speeds as low as roughly 5 Mbps. The point was to prove the training system could continue working even when the hardware underneath it was inconsistent.
The model still learned, with validation loss falling throughout the run and benchmark performance improving as training progressed.
Then They Put It on a Phone
The training experiment becomes more interesting when paired with what happens after the model is trained.
Chutes rented mobile devices through Qualcomm’s device cloud and ran the 8B model using only the phone CPU. Durbin said it reached nearly 60 tokens per second without relying on a GPU or NPU.
The team also tested a roughly 41B parameter model, which used about 12 GB of RAM and still reached close to 30 tokens per second on a phone.
On an RTX 5090, Durbin showed the architecture handling concurrent requests at almost 18,000 tokens per second.
This means useful intelligence does not always have to come from one enormous model running inside an enormous data center. Cheap smaller models can instead generate huge numbers of candidate answers, while verification systems identify the useful results.
From Data Centers to Whatever Compute Is Available
Durbin also showed how far he wants to take that idea.
One experiment had an 80B parameter model training from his backyard using a DGX Spark, solar power and Starlink. He said the architecture only needs roughly 20 Mbps of connectivity per device, making it possible to imagine training clusters built from computers spread across homes and other locations rather than one hyperscale facility.
The model architecture and training system are still being improved. Durbin said Chutes wants better data pipelines, improved routing, further attention experiments and ultimately more tokens produced for every joule of energy consumed.
But the direction is already clear.
Chutes is not only trying to decentralize access to GPUs. It is working toward an AI stack where the model itself can be trained across distributed machines, reproduced openly and then run locally on hardware people already own.
Durbin closed by describing the goal as building something closer to the open infrastructure that became the foundation of the internet.
“We need to make the Linux of AI.”
If Parallax continues moving in that direction, the important question may eventually stop being who can afford the biggest AI cluster and become how much intelligence can be produced from the billions of devices already existing around the world.
➛ Watch the full conversation below:
Enjoyed this article? Join our newsletter
Get the latest TAO & Bittensor news straight to your inbox.
We respect your privacy. Unsubscribe anytime.
Enjoyed this article?
Join our newsletter
Get the latest TAO & Bittensor news straight to your inbox — every morning before markets open.
No comments yet — be the first.