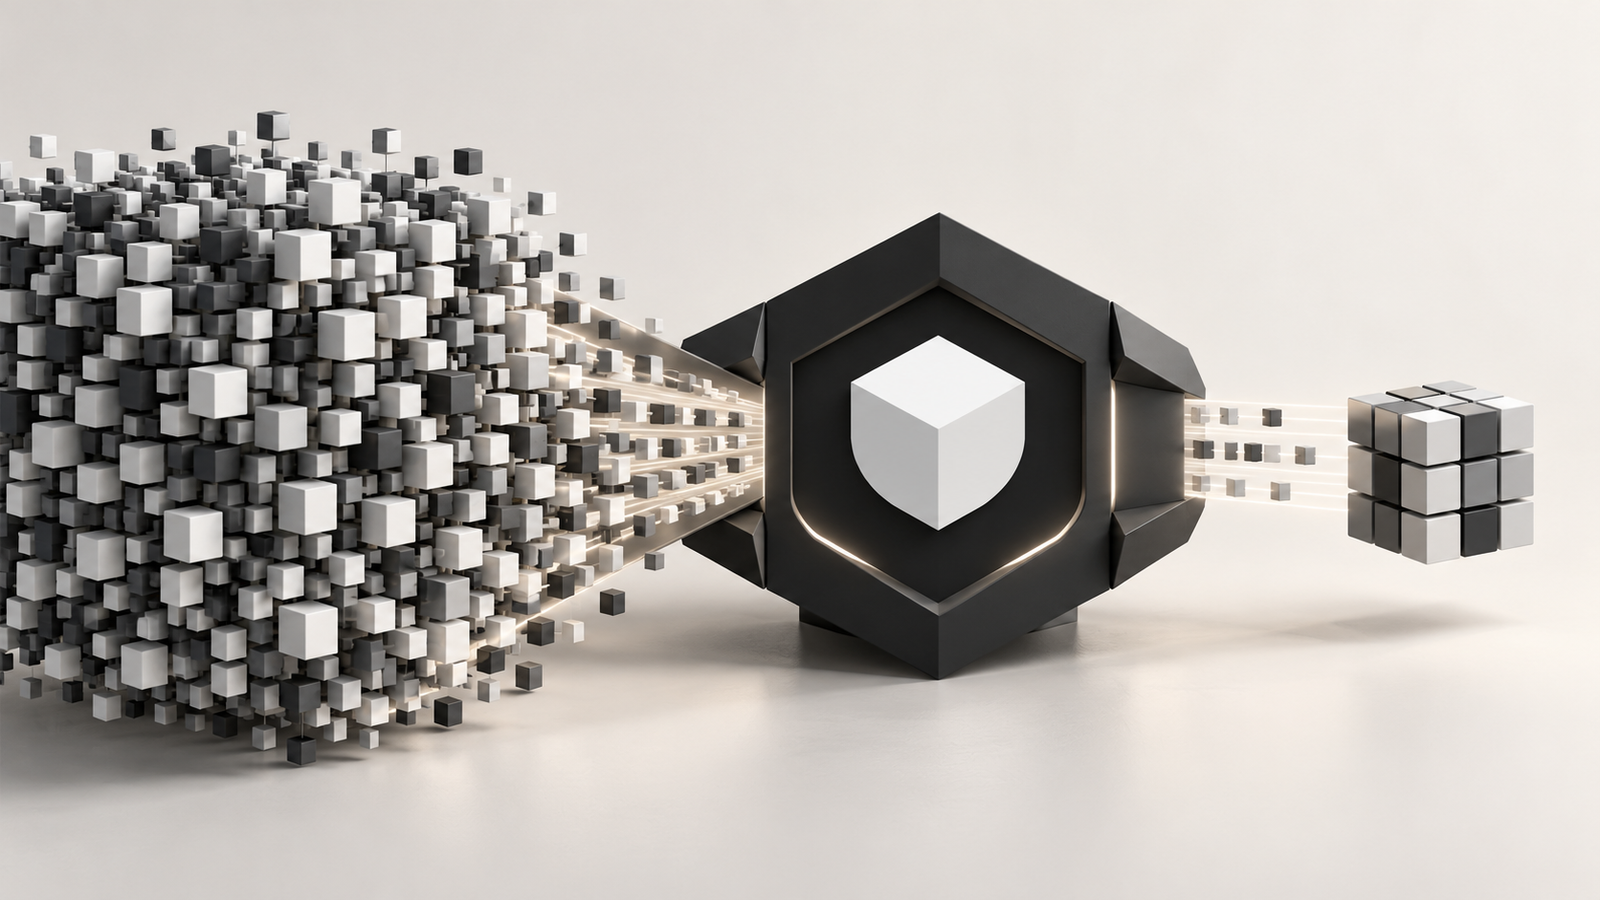
TPN (SN65) has added Quantization Aware Distillation to TPN Bench, expanding its capabilities for optimizing large language models.
The new feature allows developers and AI researchers to compress models while recovering some of the performance typically lost during compression.
It could make powerful AI models more practical to deploy on hardware with limited memory and computing capacity.
TPN (SN65) specializes in reducing the computational resources required to run AI models while maintaining their capabilities.
Its TPN Bench platform provides tools for evaluating model performance and optimizing models for deployment.
Users can upload models, select compression methods, and receive optimized versions without managing the underlying computational processes themselves.
This helps reduce the technical and infrastructure requirements associated with model optimization.
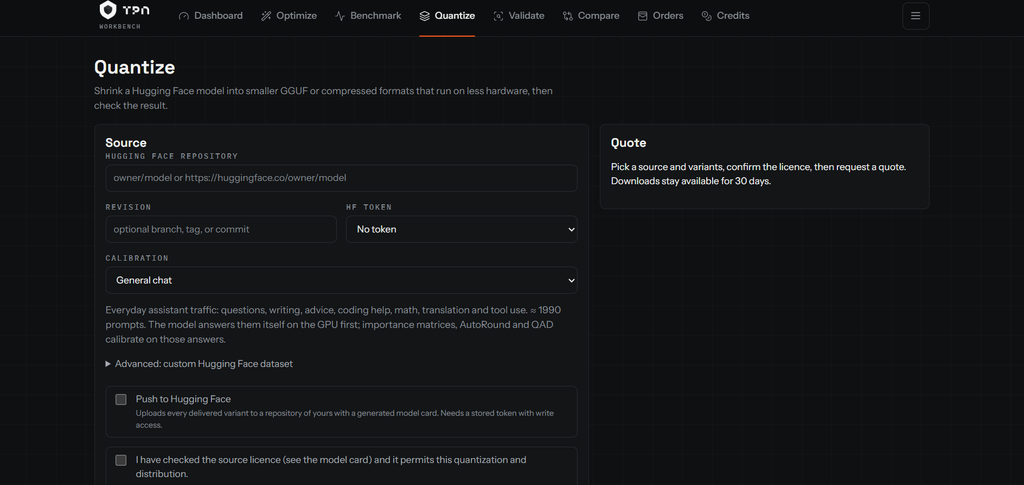
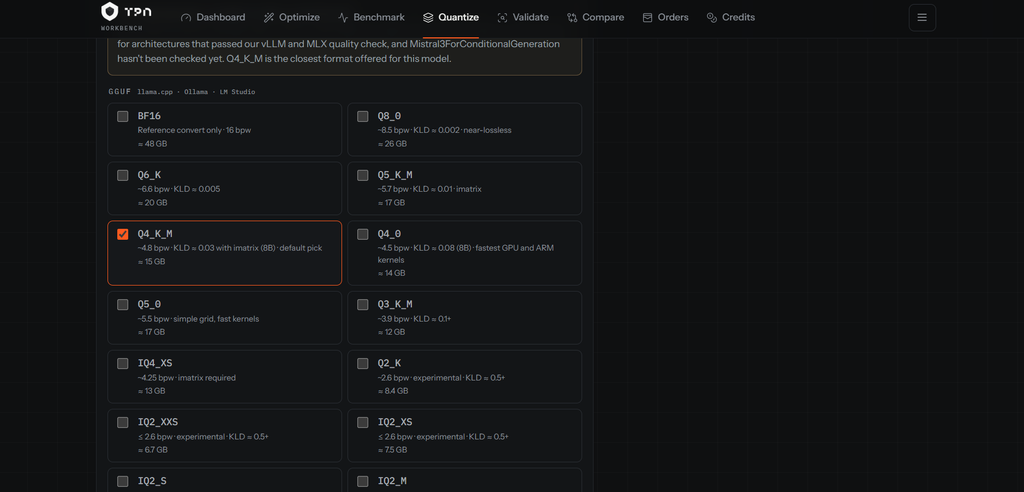
TPN Bench toolkit now offers three compression methods. Standard Quantization reduces the numerical precision of model parameters, lowering memory consumption.
I-Matrix Quantization uses information about a model’s behavior to guide precision allocation and limit performance degradation.
Quantization Aware Distillation extends these approaches by introducing additional training, allowing compressed models to recover some of the capabilities that conventional quantization can weaken.
Quantization Aware Distillation uses a teacher-student training approach in which the original model guides its compressed counterpart.
After quantization, the smaller model learns to reproduce the original model’s outputs more accurately, helping restore performance affected by reduced numerical precision.
The technique aims to combine the efficiency of smaller models with more of the capabilities found in their larger versions.
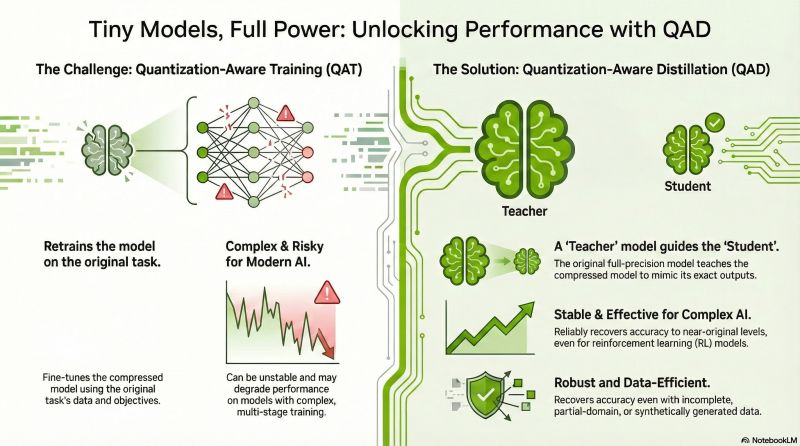
Although this approach can improve compression outcomes, the additional training requires considerable computing resources and technical expertise.
Integrating it into TPN Bench gives developers access to the process without building and managing the optimization infrastructure themselves.
For TPN, the addition expands its role in making advanced AI models more efficient and accessible across different hardware environments.
➛ Read more about the improvements to the TPN-Bench below:
Enjoyed this article? Join our newsletter
Get the latest TAO & Bittensor news straight to your inbox.
We respect your privacy. Unsubscribe anytime.
Enjoyed this article?
Join our newsletter
Get the latest TAO & Bittensor news straight to your inbox — every morning before markets open.
No comments yet — be the first.