What if developers could make large AI models small enough to run on cheaper hardware without spending hours optimizing them? TPN (SN65) has introduced a Model Quantization Toolkit that makes this possible through its TPN Bench platform.
Also called Quantization WorkBench, the service allows users to submit AI models from Hugging Face and select how they want them optimized.
TPN Bench handles the process, stores the resulting models, and provides links to download them. With permission, it can also publish the optimized versions directly to Hugging Face.
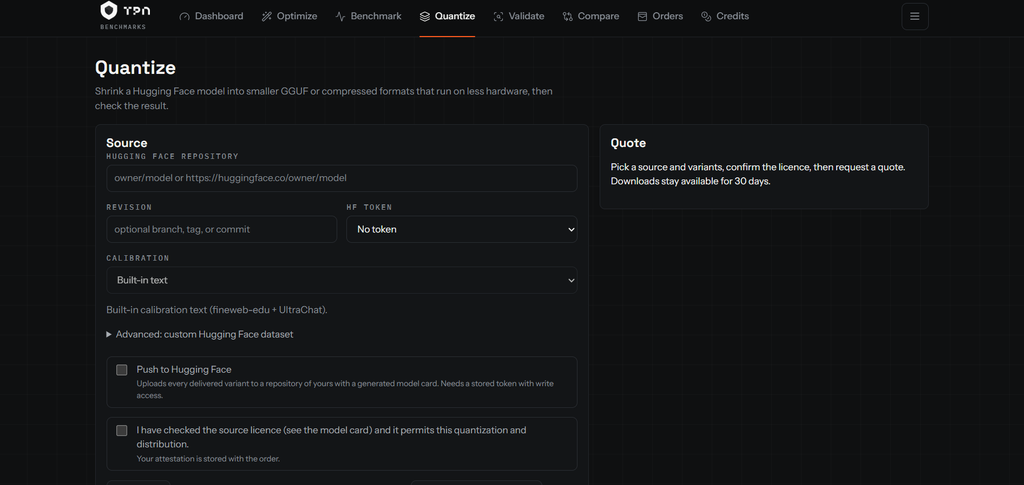
The toolkit uses a technique called quantization, which reduces the numerical precision of a model’s parameters to lower memory requirements.
This can make large models easier to run on laptops, smaller GPUs, and more affordable cloud infrastructure, although the level of performance retained depends on the method used.
Beyond standard quantization, the toolkit supports advanced methods such as I-matrix and quantization-aware distillation. These techniques aim to preserve model quality during compression and typically require specialized expertise and substantial computing resources, which TPN Bench provides through its infrastructure.
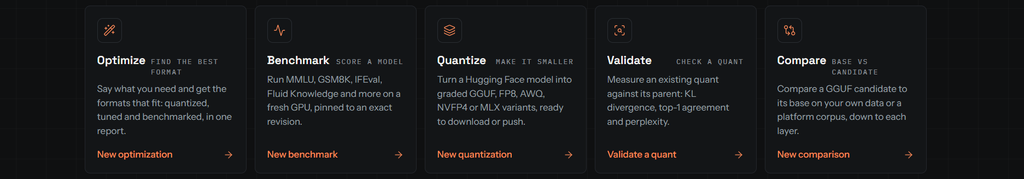
The addition expands TPN Bench beyond model testing and evaluation into model optimization. Developers can now use the platform to prepare AI models for deployment, potentially reducing the hardware requirements and costs associated with running them.
➛ Quantize Your Models on TPN Bench.
Enjoyed this article? Join our newsletter
Get the latest TAO & Bittensor news straight to your inbox.
We respect your privacy. Unsubscribe anytime.
Enjoyed this article?
Join our newsletter
Get the latest TAO & Bittensor news straight to your inbox — every morning before markets open.
No comments yet — be the first.