Bittensor subnet SayGM (SN28) has been named Provider of the Year for 2026 by TokenGauge, an independent index that compares AI model pricing across providers.
The recognition follows a comparison of 21 widely used AI models across direct providers and gateways, including OpenRouter, Requesty, Vercel AI Gateway, and SayGM.
According to TokenGauge, SayGM offered the lowest real-time inference prices for 17 of the 21 models evaluated. The platform also highlighted SayGM’s privacy infrastructure, which allows users to verify certain security claims through hardware-backed attestation.
SayGM Leads on Pricing Across Major AI Models
SayGM is a Bittensor-powered AI inference gateway that gives developers access to models from OpenAI, Anthropic, Google, and other providers through a unified platform.
Unlike accessing each AI laboratory separately, developers can use SayGM to route requests through competing infrastructure providers, with the goal of reducing inference costs.
TokenGauge’s comparison found that SayGM’s prices were 12.1% below Anthropic’s list prices for Claude models, 25.5% below OpenAI’s prices for GPT models, and 35% below Google’s prices for Gemini models.
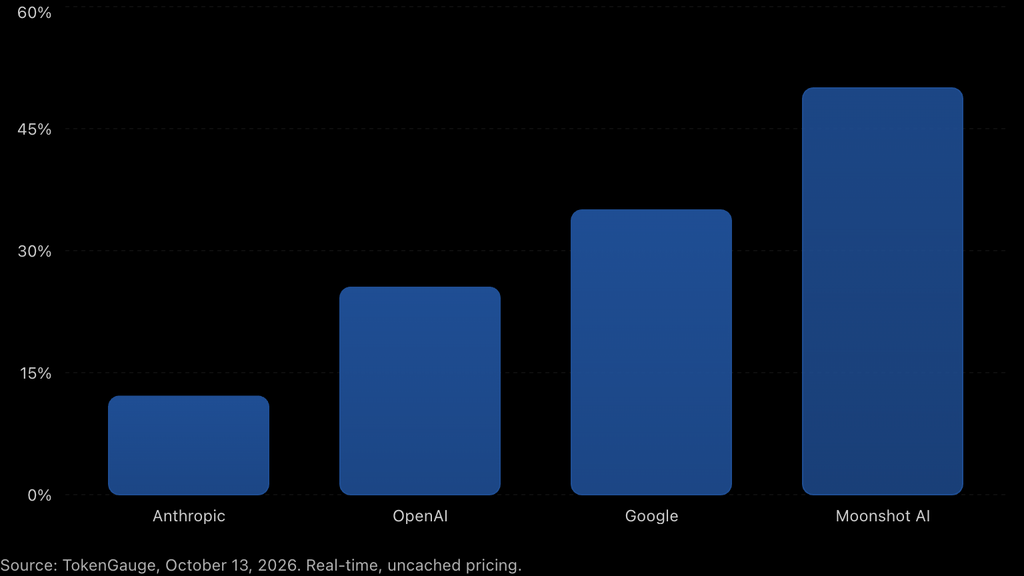
The index used a blended pricing calculation based on 80% input tokens and 20% output tokens, with applicable gateway fees included.
However, SayGM was not the cheapest option in every category. OpenRouter offered lower prices for several open-weight models (including GLM 5.3, DeepSeek V4.1 Flash, and GLM 5.3 Flash).
Some AI providers, including OpenAI and Anthropic, also offer discounted batch-processing rates that can be cheaper than SayGM, although users must wait longer to receive responses.
Privacy Infrastructure Also Contributed to the Recognition
Beyond pricing, TokenGauge highlighted SayGM’s use of Intel Trust Domain Extensions (TDX), a hardware-based security technology designed to protect sensitive information while it is being processed.
SayGM operates its gateway inside a trusted execution environment, allowing requests to be handled in an isolated computing environment. Its hardware-backed attestation system also enables third parties to check the gateway’s operating environment without relying entirely on the provider’s privacy promises.
However, this protection has limits. Requests sent to proprietary models such as Claude, GPT, and Gemini still reach their respective AI providers, while confidential open-weight deployments can offer stronger end-to-end protections.
A Recognition for Bittensor’s AI Infrastructure
The recognition brings attention to Bittensor’s growing role in commercial AI inference.
Through its subnet model, Bittensor creates competitive markets in which infrastructure providers can earn rewards for delivering useful services. SayGM applies this approach to AI inference, using competition between providers to make model access more affordable.
For developers and businesses, reducing the cost of accessing widely used AI models could make it easier to build and operate AI-powered products at scale.
Its noteworthy that the comparison is based on an October 13, 2026 pricing snapshot, and actual costs may change as providers adjust their rates.
Source: TokenGauge’s 2026 LLM API Price Index
Enjoyed this article? Join our newsletter
Get the latest TAO & Bittensor news straight to your inbox.
We respect your privacy. Unsubscribe anytime.
Enjoyed this article?
Join our newsletter
Get the latest TAO & Bittensor news straight to your inbox — every morning before markets open.
No comments yet — be the first.